In May 2025, Axios reported Kevin Mandia’s warning that an AI-led cyberattack could arrive within roughly a year, and defenders might not recognize AI’s involvement. The Mandiant founder was describing a forecast about increasing attack autonomy. His concern was serious: software could take on more of the work that currently requires an operator, while the resulting intrusion might not clearly reveal how that work was performed.
Here’s the problem: defenders already have to investigate attacks that use automation, stolen credentials and legitimate administration tools. AI can add assistance with research, scripting and deception, and agentic systems could connect more of those tasks. The danger is greater speed and scale alongside less repeated human direction. It does not depend on an attack leaving no traces, or an AI acting without an assigned goal or access to tools.
There is early evidence worth examining. The LLM Agent Honeypot study recorded 8,130,731 interactions during a three-month deployment and reported eight potential AI-driven detections. That is a tentative signal of possible LLM use in real traffic. It is not confirmation of eight distinct agents independently completing entire intrusion campaigns.
The market for AI assistance also creates reasons for concern. Products advertised under names such as WormGPT and FraudGPT promise help with criminal tasks, but a product name or seller’s claim does not verify its capabilities. Kaspersky’s September 2023 investigation documented fraudulent sites offering supposed WormGPT access. The demand for these tools and the scams surrounding them both deserve attention.
In this report, we examine what an AI-led cyberattack could change, why the warnings matter in 2025, and what the available evidence establishes. We’ll examine the Kevin Mandia prediction, the actors seeking to exploit AI, and seven warning signs that security teams should investigate. Those signs can indicate an intrusion without proving that AI is directing it.
If you want weekly breakdowns of AI threats, rogue model developments, and critical cybersecurity news, subscribe to the Quantum Cyber AI newsletter.
Key Takeaways
- AI assistance can increase the speed, scale and adaptability of offensive work; greater autonomy could reduce repeated human direction.
- Mandia’s roughly one-year warning was a forecast, and uncertainty about AI attribution does not make the intrusion itself undetectable.
- Research demonstrations, tentative field detections and seller advertisements establish different things. They should not be treated as interchangeable proof of autonomous campaigns.
- The seven signs below warrant investigation, but none by itself establishes an AI operator.
- Criminal and state-backed actors have incentives to use AI. The evidence does not establish that criminals have universally moved ahead of states.
- Behavioral visibility, access control, protected logging and model provenance remain useful. An autonomous security product is an option to evaluate, not a universal requirement.
What Is an AI-Led Cyberattack?
Defining AI-led vs. traditional cyberattacks
An AI-led cyberattack, in the fullest sense of Mandia’s warning, would delegate substantial decisions across an attack workflow to AI agents. Reconnaissance, vulnerability assessment, attempted exploitation and subsequent activity could involve less step-by-step human direction. This is a stronger claim than saying an attacker used a chatbot to write an email or troubleshoot a script.
What sets agentic systems apart from a fixed script is their ability to use model outputs to choose among actions and respond to feedback. A May 2025 research survey, Forewarned is Forearmed, examines offensive applications, demonstrations and limitations of LLM-based agents. Its synthesis supports concern about increasingly capable automation; it does not establish that every part of a real attack can reliably run without human involvement.
These agents still operate within a configured workflow. Someone provides goals, instructions, tools and permissions. Reduced intervention during a task should not be confused with an unconfigured system spontaneously deciding to attack. For a defender, the relevant questions are what actions were possible, what access was obtained and how the operation could be interrupted.
The emergence of autonomous AI hacking agents
Autonomous AI agents are software systems that combine planning, decision-making and execution through tools. The May 2025 survey discusses research on these capabilities. It brings together work on capabilities, demonstrations and limitations across the field.
The honeypot study provides a different kind of evidence: possible AI involvement in observed traffic. Its eight potential detections are worth investigating, while the authors’ detection limits matter. Neither that count nor a demonstration in a controlled environment can tell an employer that a particular unexplained intrusion was autonomous.
The concern about lower barriers remains. Assistance with language, research and code can make some tasks easier to attempt. How much it helps depends on the task, the attacker’s judgment and the access available. That is a practical risk even before dependable, fully hands-off campaigns are established.
Why greater autonomy matters
An AI-led cyberattack could make parts of an operation faster and more adaptable. Traditional attack detection includes known signatures and indicators, but also behavior, identity and activity across systems. An attacker’s use of AI does not automatically bypass those controls.
The harder problem is recognizing harmful activity when familiar tools and accounts are used in an unfamiliar sequence. A defender may see the attempted access or data movement without knowing whether a human selected each action. Investigation can proceed on that evidence without first solving the AI-attribution question.
The distinction matters for investment. Organizations need visibility into what happened and the ability to restrict access or contain activity. They do not need to reconstruct an attacker’s entire decision process before responding. AI may complicate the workload without making all existing evidence irrelevant.
Our coverage of AI-powered malware threats discusses the related concern that AI assistance can change offensive work. The useful question is which behavior a defense can observe and interrupt, rather than whether a tool carries an AI label.
Why 2025 Is Raising Concerns About Autonomous AI Hacking
Rogue-model advertising and AI-assisted coding
The cybersecurity community has seen criminal interest in large language models marketed without the restrictions of mainstream services. WormGPT and FraudGPT are prominent names in that discussion. Advertising for such products should be distinguished from evidence that a particular advertised feature works, or that it can conduct a complete attack independently.
In WIRED’s June 4, 2025 reporting, AI-assisted coding and agent development raised concern about easier offensive automation. The discussion of “vibe hacking” concerns using AI to help build code and tools.
WIRED’s prospective scenarios are a warning about where these systems could go. They should not be read as proof that completely hands-off replacement of human offensive operators was already routine. The difference between a useful assistant and a reliable autonomous operator is central to assessing the threat.
Europol and Darktrace’s forecasts for AI-assisted crime
Europol’s March 2025 threat assessment describes AI increasing the efficiency, speed, reach and sophistication of organized crime. Deepfake fraud and other scalable forms of deception give that warning practical importance. The report also describes blurred boundaries between criminal and state interests.
Darktrace’s predictions for 2025, published in November 2024, anticipated adversarial adoption of AI agents and risks involving AI systems. Those were earlier vendor forecasts, not reactions to Mandia’s later interview or proof that autonomous criminal operations were already happening at scale.
Together, these warnings support preparation for more AI-enabled offense. Their significance lies in the prospect of more capable and accessible assistance, with greater autonomy still an emerging concern. A forecast can justify preparation while remaining distinct from an observed incident.
Easier assistance does not remove every barrier
The attraction of AI for attackers is partly economic. If an assistant reduces the time needed to draft messages, understand unfamiliar material or revise code, it can change the cost of attempting those tasks. The effect on a particular operation depends on whether that assistance is useful and whether attempted actions succeed.
An operation still depends on such factors as available access, the target’s weaknesses and whether attempted actions succeed. A seller’s list of exploit-generation or stealth features cannot answer those questions. Unverified prices and package contents are a poor basis for estimating an organization’s exposure.
The institutional concern is cumulative: useful assistance can be repeated, and workflows may become more automated. Security teams should prepare for that pressure while distinguishing it from claims of near-zero skill requirements or invisible agents already inside every network.
To understand just how seriously the industry takes this moment, we need to examine one of the loudest voices raising the alarm: Kevin Mandia.
Kevin Mandia’s Warning: What It Really Means
What Mandia said, and why it matters
Axios’s May report followed an interview around the April RSA conference. Mandia anticipated an AI-led attack within roughly a year and questioned whether defenders would recognize AI’s role. His warning concerned the possibility of greater autonomy and the difficulty of recognizing AI’s role from the resulting activity.
Mandia’s credibility comes not just from his role as a company founder, but from his hands-on experience investigating breaches involving state-sponsored hackers, ransomware gangs, and espionage groups. His teams were responsible for exposing the SolarWinds campaign and other high-profile breaches. When someone with his track record warns about increasing attack autonomy, the industry has reason to take the possibility seriously.
What makes his statement especially significant is the convergence it describes: AI assistance is useful to adversaries, agentic research is advancing, and detection and response already involve difficult judgments. The warning deserves attention without turning the forecast into a claim that every capability has been demonstrated in criminal operations.
Why he expected criminal groups to move first
While it’s tempting to assume that only nation-states have the resources to deploy autonomous AI hacking tools, Mandia’s expectation pointed toward cybercriminals. This was his forecast about likely incentives and adoption, not an established finding that criminal groups had already surpassed all state-backed operators.
Criminal groups have a financial reason to seek cheaper, repeatable assistance. That incentive helps explain the concern about AI-enabled crime. It does not make the activities of intelligence services and criminals mutually exclusive, or establish that either category uses a single technical approach.
These groups also don’t need perfect AI, they need useful AI. Help with producing text, researching a target or resolving a coding problem can have value without replacing an entire operation. The possibility that more of this work could be connected into an agentic workflow is the risk Mandia was asking defenders to anticipate.
Earlier warnings and the attribution problem
Darktrace’s earlier predictions and Europol’s assessment reflect related concerns about AI’s effect on adversaries. Their different dates and purposes matter: Darktrace anticipated agentic risks, while Europol assessed AI’s potential to strengthen organized crime.
One difficult question is how investigators would distinguish assistance from autonomy after an intrusion. Evidence may establish unauthorized activity without showing which decisions were made by a model. That uncertainty can complicate analysis while leaving plenty of reasons to contain the incident and protect affected systems.
The warning is therefore actionable before attribution is complete. Organizations can examine the access, behavior and consequences they observe while keeping claims about an AI operator proportionate to the evidence.
How AI Could Complicate Detection and Attribution
Configured goals and autonomous planning
One of the concerns behind an AI-led cyberattack is that an agent could carry out a sequence of tasks with less repeated human direction. The system still needs a goal and an operating environment. Calling it “promptless” obscures the instructions, permissions and tool access that make its actions possible.
The May 2025 survey describes research on offensive agent capabilities and their limitations. Controlled demonstrations can help identify risks while leaving questions about performance against a real organization. An agent’s success in one task does not by itself establish reliable, independent execution of an entire intrusion.
For an organization, the important distinction is between a model generating suggestions and a system allowed to execute them. A workflow that connects outputs to actions can create more exposure than a text-only answer. The risk depends on the authority and access around the model as well as its capabilities.
Sleeper-agent triggers and model backdoors
Another concern involves models trained to behave differently when a particular trigger is present. In January 2024, Anthropic’s sleeper-agent researchers deliberately constructed proof-of-concept models with trigger-dependent behavior and tested whether specified safety-training methods removed it.
The result raises a serious model-supply-chain concern: reassuring behavior in ordinary testing is not enough to establish that every harmful conditional behavior has been removed. The experiments do not establish that all such behavior is undetectable or that a conventional sandbox universally fails. They also do not document a criminal deployment of the same research models.
The relevant warning is to examine how a model was obtained, trained and integrated. The laboratory demonstration gives a concrete reason for care about conditional behavior and the limits of safety training. Assessing a deployed model still requires evidence about that model and its surrounding workflow.
Anti-forensic actions and established intrusion techniques
Attackers can try to conceal their activity whether or not they use AI. The February 2024 joint living-off-the-land guidance describes state-backed operators hiding through legitimate tools and recommends behavioral baselines, protected logs and appropriate access controls.
Examples of activity that should concern investigators include missing logs, unexpected changes to timestamps or system settings, and suspicious use of legitimate administration utilities. AI assistance could help an operator plan or automate parts of an operation. The behavior itself does not establish that an AI made the decisions.
These techniques can make post-incident analysis difficult. An investigation needs the available evidence across systems, rather than an assumption that an unfamiliar pattern must be AI. Protected records can preserve part of the sequence even if evidence on a compromised device is damaged or lost.
Blending patterns and uncertain attribution
Attribution is a cornerstone of modern cybersecurity response. It helps identify attackers, inform public policy, and prioritize defenses. AI assistance could add to an already difficult task if different parts of an operation no longer resemble one consistent operator’s work.
That possibility does not make attribution obsolete. A mixture of tools, infrastructure and behavior calls for investigation rather than a ready-made conclusion about its origin. Recognizing uncertainty is more useful than assigning national or organizational responsibility from a superficial resemblance.
Understanding these risks is essential while retaining the value of ordinary indicators of compromise. To see why increasing accessibility matters, it helps to revisit the connection between earlier automation and today’s concern about agentic systems.
From Script Kiddies to Super Agents: The Evolution of Cybercrime
A brief history of low-skill automation
Mandia’s comparison included Russian actors using scripts to automate eBay fraud in 2001. It illustrated how software could repeat work that had previously involved more manual effort.
These early tools required minimal understanding of how systems worked. Attackers simply downloaded scripts, input targets, and launched attacks without grasping the underlying mechanics. The key innovation wasn’t technical sophistication, it was accessibility.
The concern about AI follows that same logic. Assistance can make a task easier to attempt, and agentic systems could connect tasks into a more adaptable sequence. This is a reason to examine the impact of automation without assuming every advertised capability is dependable.
Mandia’s historical comparison to early hacking tools
Kevin Mandia draws a direct parallel between these early script-based attacks and the rise of AI-led cyberattacks. The comparison asks what changes when a tool can help choose the next action instead of merely repeating a fixed sequence.
In that forecast, greater autonomy is the important possibility. An operator could delegate more decisions while providing the objective, access and surrounding infrastructure. The distinction matters because useful automation may increase reach even when it still makes errors or requires intervention.
This comparison isn’t just rhetorical. Defenders already cannot assume that removing one tool ends an attack; an attacker may retain access to another system. AI assistance could complicate this established incomplete-containment problem by helping the attacker refine tactics and adapt activity.
AI’s leap: from automated scripts to adaptive workflows
Agent frameworks can connect a model’s outputs to tools and carry information from one step to another. The offensive potential discussed in the research is the ability to make parts of that workflow less dependent on repeated human input. That does not establish that any named general-purpose framework is itself a proven criminal campaign platform.
The May 2025 survey brings together research on capabilities and limitations. A successful demonstration in a controlled task is relevant to preparation, but it does not prove reliable exploit discovery, evasion and independent execution against every real target.
Adaptation also does not necessarily mean a model is continuously retraining itself during an operation. A system can choose a different action using feedback within its existing workflow. Defenders should focus on the actions and access involved rather than infer a particular learning mechanism from the result.
How attackers could scale assistance
Commercialized AI assistance creates an incentive to package useful functions for other actors. Help with text, research or scripting can lower the effort needed for parts of an operation. Those functions do not remove the need for judgment or establish the seller’s promise of a complete, autonomous attack.
The marketplace therefore presents two related problems: harmful assistance may be offered for sale, and buyers may encounter exaggerated or fraudulent offerings. The fake WormGPT-access sites documented by Kaspersky illustrate why advertisements cannot be treated as independent confirmation of technical capability.
It’s cybercrime-as-a-service, and it’s why defenders must start thinking beyond malware signatures. The question is how assistance changes the workload and decisions involved in an attack, rather than whether a low advertised price makes compromise inevitable.
Who’s Behind It? Cybercriminals and State-Backed Actors
Evidence of state-backed actors using commercial AI
Google’s January 2025 findings describe government-backed groups using the Gemini application for research, scripting, troubleshooting and content. Chinese and Iranian actors in that report should not be relabeled as proof that financially motivated criminals were first.
Google reported productivity benefits without observing novel capabilities in its dataset. That finding does not show that those actors trained Gemini clones or ran independent agent campaigns. It also cannot establish that autonomous activity was absent everywhere outside the observed data.
The report’s account of APT42 includes research on experts and organizations and assistance with tailoring or localizing phishing material. These activities illustrate how AI can make established social-engineering work more efficient. They also show why apparent familiarity with a target’s professional interests is not enough to establish a message’s legitimacy.
Europol’s warning about AI-enabled crime
Europol’s assessment supports the concern that AI can increase organized crime’s reach and efficiency. It does not establish that criminal AI adoption is universally faster than state use. Its discussion of blurred criminal and state interests also cautions against treating those categories as neatly separate.
Financial incentives help explain why criminal networks would pursue tools that reduce effort or improve deception. That is an argument about incentives, not a measurement showing that one class of actor has become more technically capable than every other class.
The institutional response should account for both. An organization can be exposed to criminal fraud, state-backed activity or overlapping interests, and AI assistance may appear in any of them. The investigation still has to establish what the evidence supports.
Profit and politics: different incentives, overlapping tools
State-sponsored attacks often have strategic or political objectives, long-term espionage, infrastructure disruption, or military advantage. Criminals, on the other hand, are driven by profit. AI assistance can be attractive when it helps either type of operator do useful work more efficiently.
Examples of assistance supported by the research and reporting include:
- Drafting or adapting persuasive text.
- Helping with research about systems, organizations or people.
- Producing or troubleshooting scripts and code.
- Connecting tasks in workflows that may involve less repeated direction.
Those uses can matter without proving that an entire intrusion was autonomous. The incentive to increase volume, speed and useful output is sufficient reason to prepare. It is also a reason to distinguish a forecast about future autonomy from the evidence for particular activity.
The new black market: AI assistance as a service
Products sold under names such as WormGPT and FraudGPT are part of the commercialization concern. Their advertised promise is assistance with tasks that buyers may use for crime. Advertising, a subscription interface or a support offer does not establish that every claimed function is available or effective.
A product name cannot establish that a purported bundle of functions works. Sellers have an incentive to present a service as powerful and easy to use. Investigators and decision-makers need to distinguish those promises from demonstrations and independently observed results.
This distinction does not make the market harmless. Easier access to useful assistance can increase the pressure on organizations, even when sellers exaggerate. Defenders need to understand what the tools actually enable and respond to observed activity rather than treat advertising as incident evidence.
7 Early Signs to Investigate in a Possible AI-Led Cyberattack
The following signs concern activity that can occur in an intrusion. AI may help an attacker carry out parts of it, but the signs are not a reliable test of AI authorship. Responding to harmful behavior does not require settling that question first.
1. Unusually fast and broad reconnaissance
Unexpected scanning or probing across services can be an early sign worth investigating. Machine-speed activity is not new, and a fast scan does not prove that an AI agent selected the targets. The useful questions concern what was accessed, whether it was authorized and how it differs from expected operations.
Research on agentic systems raises the possibility of more flexible task selection and feedback. The LLM Agent Honeypot study’s observations need to be interpreted within its method and tested conditions. Its potential detections offer an early observation of possible LLM use, with the study’s stated uncertainty.
Broad or unusual reconnaissance can still warrant attention. Compare it with normal behavior and other evidence instead of assuming a particular model or attacker. Speed can affect workload without making the activity invisible to monitoring.
2. Morphing malware signatures
Changing code or signatures can complicate detection based only on a known file. AI assistance may help an operator produce or revise code, but polymorphism and conditional behavior do not require AI. A different hash by itself cannot establish an AI-led cyberattack.
The question is what the program does, how it arrived and what other activity surrounds it. Behavior and identity evidence remain relevant alongside signatures. An organization should not conclude that all endpoint tools are ineffective because a sample differs from a previously known one.
WIRED’s discussion of possible future agents raises concern about more adaptable offense. Conditional behavior based on an environment or time is not exclusive to AI. Investigators should examine what a program does without inferring its origin from one change in behavior.
3. Deepfake-based social engineering
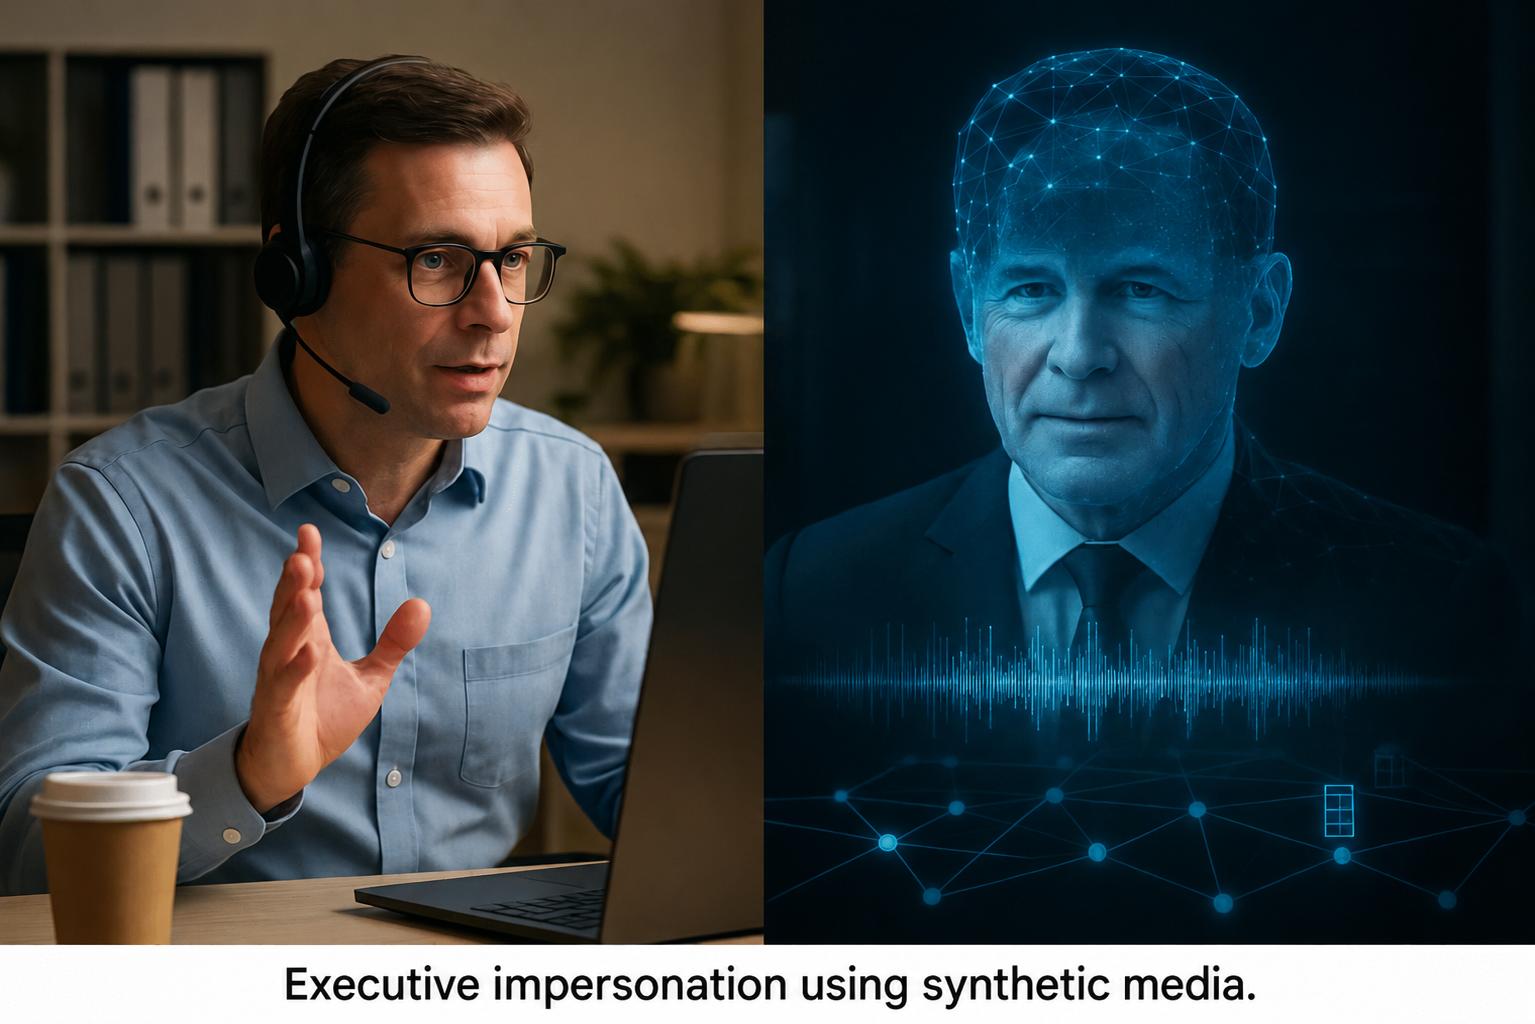
Social engineering has always been a cornerstone of cybercrime, and synthetic media can make an impersonation convincing enough to facilitate fraud. The danger does not require a flawless voice or a fully autonomous system. A convincing message or apparent executive presence can be enough to influence a decision.
Hong Kong’s June 2024 official account described a January incident involving a fabricated video meeting impersonating a UK chief financial officer, followed by payment instructions through messaging. It described prerecorded video without interaction during the meeting. The account does not establish a live CEO dialogue or identify Zoom.
A familiar face or voice is therefore not sufficient authorization for an unusual transfer or access request. An employee should use the organization’s established verification route. The action being requested matters as much as the apparent identity of the person asking.
4. Persistence across endpoints and lateral movement
Unexpected activity spreading across systems, or access that returns after one route is closed, warrants investigation. AI could assist an operator with parts of this work, but persistence and lateral movement are established intrusion concerns. Neither behavior proves autonomous control.
Investigators need to examine the accounts, access paths and devices actually involved. A return of activity could indicate another route of access or incomplete containment. The response should follow that evidence instead of assuming a particular autonomous mechanism.
This kind of persistence is difficult to counter, particularly if the attacker doesn’t deploy known malware but instead operates through legitimate tools like PowerShell, Python, or Bash, blending into IT operations.
5. Attribution tools return false positives or blanks
Uncertain attribution can complicate a response, but it is not an AI detector. Different tools, infrastructure and operating patterns can point in different directions. A blank result or conflicting classification does not establish that a model is intentionally combining national threat groups’ signatures.
Analysts should retain uncertainty rather than treat a superficially familiar pattern as proof of origin. Evidence for malicious access can be stronger than evidence identifying the operator. Keeping those judgments separate helps a response move forward without overstating attribution.
Containment need not wait for that final attribution judgment. The affected organization can respond to the access and consequences it has established while investigators continue examining who was responsible and how much automation was involved.
6. Simultaneous exploitation attempts and vulnerability chaining
Several probes or attempted exploits close together can create a difficult investigative workload. They do not prove that an AI discovered multiple new zero-days or independently chained them against a live target. Research demonstrations and benchmark results have to be interpreted within their tested conditions.
The May 2025 survey discusses work relevant to offensive capabilities under different research conditions. A report of success in those conditions is not the same as a confirmed operation against a live organization. Defenders should investigate the vulnerabilities, attempted actions and affected systems for which they have evidence.
The risk remains that assistance and automation can increase the number of tasks an adversary attempts. That concern supports visibility across systems and a coordinated response, especially when separate alerts may be parts of one operation.
7. Log deletion and forensic evasion
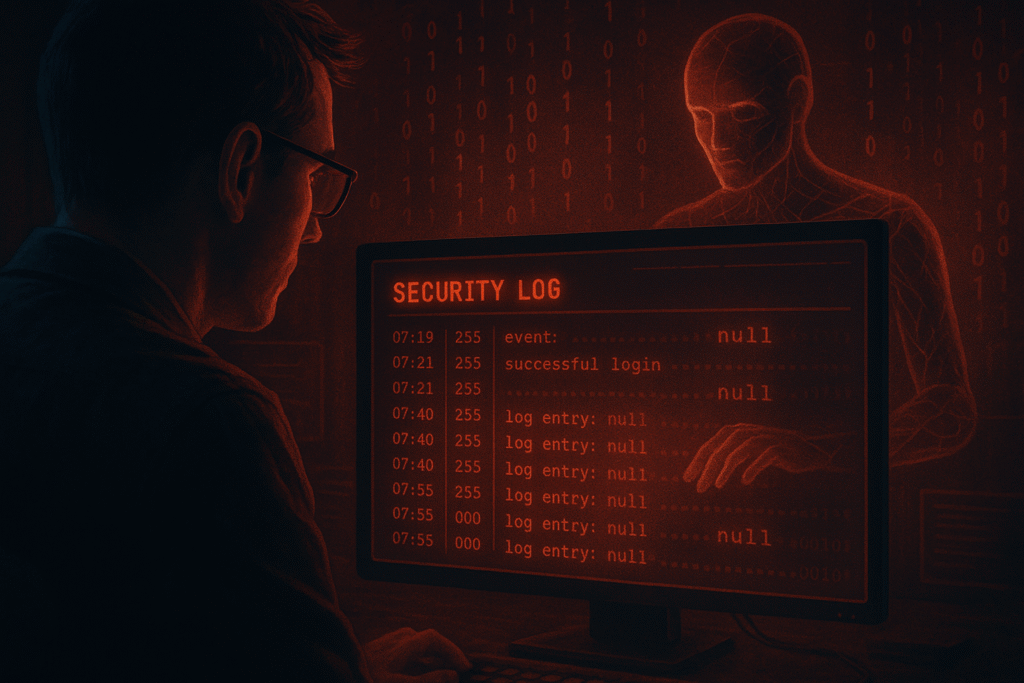
Finally, perhaps the most damaging warning sign is what’s missing: the logs. Unexpected gaps, disabled logging or changes inconsistent with normal administration can undermine an investigation. These are reasons to examine what happened, regardless of whether AI assisted the actor.
Losing a local record can deprive investigators of an important part of the sequence. Logging interruptions therefore deserve explanation. Their significance depends on what other systems recorded and whether the gap has an authorized operational cause.
Preserve and compare the available evidence across systems. The goal is to understand the activity and its consequences, rather than conclude that missing information proves an invisible autonomous adversary. Protected logging remains an important defense.
Understanding these signs isn’t enough; you must also act on them. Our 2025 overview of AI-powered cybersecurity tools provides related background on the tool categories. Evaluate coverage and operational fit rather than treat an AI label as proof that a product can stop every attack.
How to Prepare: Tools, Mindsets, and Mistakes to Avoid
Evaluate agentic defenses alongside existing controls
Security information and event management systems, endpoint tools and human investigation remain relevant. Multinational event-logging guidance published in August 2024 includes SIEM correlation, endpoint detection, anomaly detection and threat hunting. The need is to configure and use those capabilities appropriately.
Agentic security products may offer assistance or automation, but organizations should evaluate their permissions, limits and evidence of useful performance. Not every product retrains during operation, and autonomy does not make a decision correct. The consequences of a mistaken response matter as well as response speed.
No universal requirement to buy an autonomous defense follows from the research discussed here. Consider what the organization can observe and contain, what staff can investigate and which gaps remain. A proposed addition should improve that operation rather than merely match an attacker’s marketing language.
Our 2025 coverage of AI security tools and emerging attacks provides related context. It should support questions about a tool’s role, not substitute for evidence that the tool fits a particular environment.
Treat LLM honeypots as a research and telemetry option
The LLM Agent Honeypot study shows an attempt to detect possible AI use in incoming activity. Its limited potential detections and the authors’ stated limitations are important. This is exploratory work, not a demonstrated guarantee of identifying every autonomous agent.
Decoys may add useful telemetry when an organization has the expertise to design, contain and monitor them. The value depends on what they record and how that evidence is interpreted. An unusual language pattern or response is not enough by itself to identify an AI operator.
Organizations considering such techniques should keep the distinction between observation and attribution clear. Honeypot evidence can contribute to an investigation; it should not replace protected logging, identity controls or response planning across the actual production environment.
Monitor LLM supply chains for backdoors
A growing concern lies not just in rogue attackers, but in the models organizations deploy. Anthropic’s deliberately constructed sleeper-agent experiments show why ordinary reassuring behavior may not settle every question about a model’s training and conditional behavior.
The practical lesson is to examine the provenance of a model and any modification before connecting it to sensitive work. The experiments concern deliberately trained proof-of-concept behavior, so their application to a deployed model depends on that model’s provenance, training and integration.
To reduce exposure, organizations should:
- Check the provenance of models and modifications before deployment.
- Where they train or fine-tune models, keep reproducible records and audit logs.
- Monitor model behavior in real-world usage, not just test cases.
If your AI stack includes external or third-party models, especially in customer service, threat detection, or fraud prevention, the surrounding access and permissions deserve attention. A model’s output should not automatically receive the authority to carry out an action simply because ordinary tests appeared reassuring.
Prioritize visibility across the kill chain
Reconnaissance, initial access, lateral movement and later activity give defenders different opportunities to observe an intrusion. Lateral movement is not an early reconnaissance step, and AI does not remove the value of monitoring any of these stages.
Organizations can examine unexpected behavior and connect it across systems before the full purpose of an operation is clear. Useful work includes:
- Mapping normal internal traffic baselines to detect unusual scanning.
- Logging failed lateral movement attempts, even across low-privilege accounts.
- Tracking system calls and process creation logic for abnormal chaining.
Focusing on these patterns can help reveal harmful activity without first establishing whether AI was involved. It’s a proactive mindset, not a reactive one. The objective is useful evidence and a workable response across the organization.
Conclusion: Prepare for Greater Attack Autonomy
AI assistance is already relevant to offensive work, and research on agents raises serious questions about how much more of that work could be delegated. Organizations should prepare for attacks that become easier to attempt, more repeatable or more adaptable. That warning is strong enough without claiming that every autonomous capability has already been verified in the wild.
Mandia’s roughly one-year forecast expresses concern about both attack autonomy and recognizing its role. The available research and reporting establish different pieces of the problem: useful assistance, controlled demonstrations, tentative field detections and marketplace interest. Together they justify attention while leaving important uncertainties about reliable full-campaign autonomy.
The seven signs in this article are reasons to investigate harmful behavior. They are not proof of AI authorship. A defender may see suspicious access, changing code or missing records while remaining uncertain about who selected the actions. Response can proceed on the evidence available.
The path forward includes behavioral visibility, protected logging, controlled access and careful model integration. Policymakers, meanwhile, must get serious about regulating the proliferation of unsafe models and developing standards for attribution, model traceability, and post-breach accountability.
Waiting for a catastrophic breach before preparing would be a serious mistake. The task is to act on the risk while being clear about what has been observed, what has been demonstrated and what is still a forecast.
FAQ
What makes an AI-led cyberattack harder to detect than a human one?
AI assistance could help an attacker vary or connect tasks with less repeated direction. That can complicate the workload, but it does not make an intrusion inherently invisible. Access, behavior, endpoint activity and protected logs remain relevant even when investigators cannot establish how the attacker made each decision.
Are these rogue AI models available publicly?
Services are advertised under names such as WormGPT and FraudGPT, but advertisements do not independently verify their capabilities. Fraudulent access offers also exist. A seller’s promise of autonomous hacking should not be treated as evidence that the advertised system can reliably perform a complete operation.
Are major AI labs responsible for these threats?
Misuse can involve commercial services as well as modified models. Google’s reported observations of government-backed actors using Gemini show why the risk cannot be assigned exclusively to open-source clones. The degree of assistance or autonomy in a specific case requires evidence.
What are some examples of AI being used in crime in this historical coverage?
The examples include convincing synthetic impersonation and assistance with research, phishing material and code. The Hong Kong payment-fraud account and the observed uses in Google’s report establish particular activities. They do not by themselves demonstrate an independent AI running an entire intrusion campaign.
How can I protect my organization from this threat?
Improve visibility, access controls, protected logging and response processes, while examining the provenance and permissions of any models you deploy. Evaluate agentic products or decoys for a defined role and with evidence of their limits. Do not wait to identify an AI operator before investigating harmful activity.